
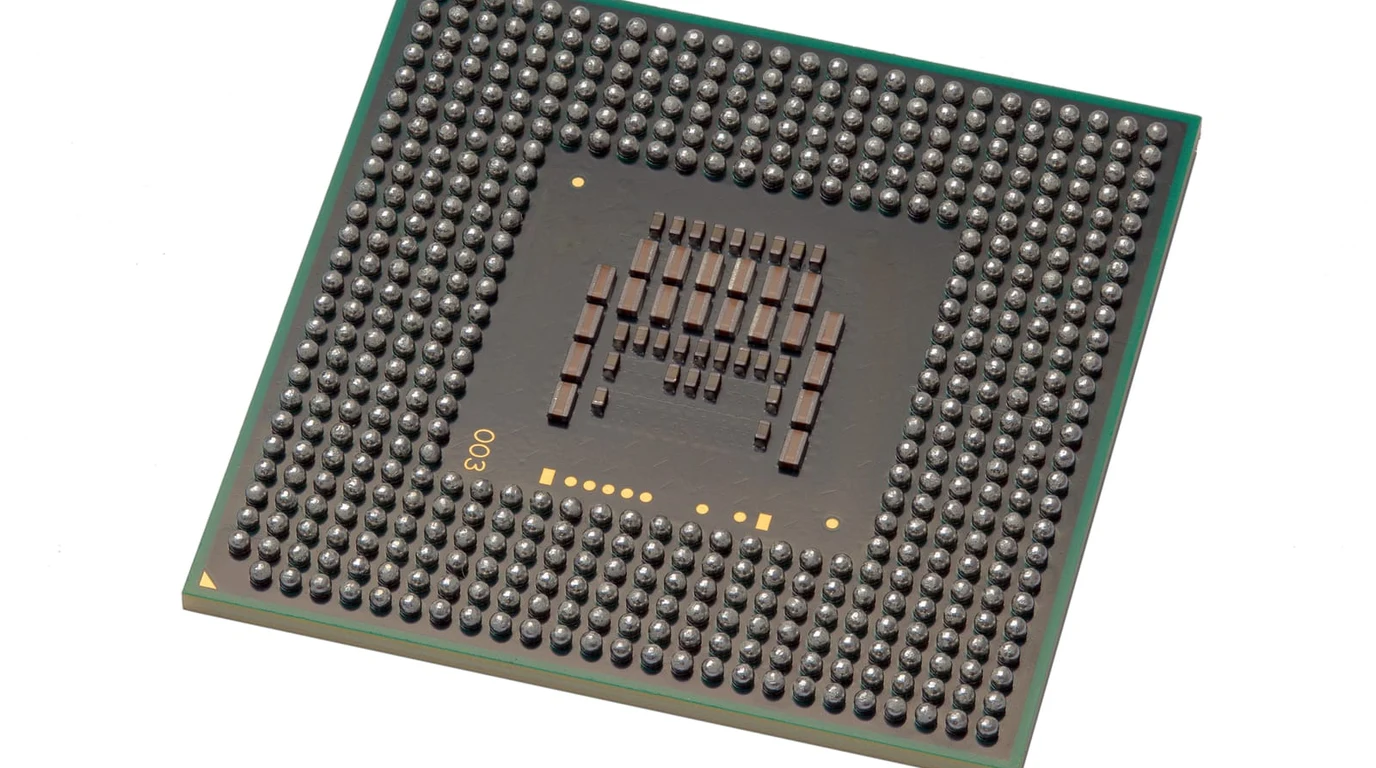
For systems architects, computer vision engineers, and homelab builders deploying edge AI inference, the physical hardware landscape has reached an inflection point. For nearly six years, the Google Coral Edge TPU (PCIe/M.2) was the undisputed, default hardware accelerator for local object detection. Delivering 4 TOPS (Tera-Operations Per Second) of INT8 tensor compute on a frugal 2-watt power envelope, the Coral powered thousands of Frigate NVR surveillance rigs and industrial edge gateways. However, as deep learning models transition from lightweight MobileNet detectors to multi-head transformer architectures and high-resolution YOLOv8 models, the Coral’s 28nm silicon is buckling under memory bandwidth bottlenecks. Enter the Hailo-8 M.2 AI Acceleration Module, delivering a staggering 26 TOPS at under 2.5 watts. How do their microarchitectures, neural compilers, and real-world inference latencies compare?
What Is the Difference Between Google Coral Edge TPU and Hailo-8?
The Google Coral Edge TPU utilizes a fixed systolic array architecture delivering 4 TOPS INT8 compute via PCIe Gen2 x1, restricted to 8-bit quantized TensorFlow Lite models with strict operator support. The Hailo-8 utilizes a revolutionary structure-driven Dataflow architecture delivering 26 TOPS INT8 compute via PCIe Gen3 x4, executing full YOLOv8 and transformer pipelines with sub-5ms latency while compiling natively from PyTorch and ONNX through the Hailo Dataflow Compiler.
To understand why the Hailo-8 outperforms the Coral by more than 6x in compute density, one must analyze their fundamental silicon execution models. The Google Coral Edge TPU operates on a classic systolic array paradigm, originally pioneered by Google’s cloud TPUs. Data streams sequentially through a grid of multiply-accumulate (MAC) units. While highly efficient for simple convolutional layers with uniform kernel sizes, systolic arrays require constant external memory shuffling from host RAM. When running modern models with depthwise separable convolutions or attention mechanisms, the Coral spends significant clock cycles waiting for memory transfers over its PCIe Gen2 x1 link, creating severe memory-bound latency spikes.
The Hailo-8 fundamentally abandons the von Neumann architecture and systolic grids in favor of a Structure-Driven Dataflow architecture. Hailo’s silicon consists of thousands of distributed, tiny compute, memory, and control units interconnected by a programmable network-on-chip (NoC). Instead of cycling instructions through a centralized ALU and fetching weights from external RAM, the Hailo Dataflow Compiler (HDC) maps the computational graph of the neural network directly onto the physical layout of the silicon chip. Each layer of the neural network occupies a specific physical zone on the die. Intermediate activations flow directly from one physical core to the adjacent core through local high-bandwidth SRAM without ever touching host system memory.
Google Coral vs Hailo-8: Silicon Architecture & Benchmark Matrix
Comparing compute density, PCIe interfaces, framework compatibility, and real-world vision model performance:
| Silicon Metric | Google Coral Edge TPU (M.2 Key E/M) | Hailo-8 AI Module (M.2 Key M 2280/2242) | Architectural Advantage |
|---|---|---|---|
| Peak INT8 Compute | 4 TOPS (Tera-Ops / Second) | 26 TOPS (6.5x Compute Density) | Hailo-8 processes multi-stream 4K pipelines effortlessly. |
| Silicon Process Node | 28 nm CMOS (Legacy TSMC) | 16 nm FinFET (High-Density TSMC) | Hailo achieves dramatically higher power efficiency (TOPS/W). |
| Host PCIe Interface | PCIe Gen2 x1 (5.0 GT/s / 500 MB/s) | PCIe Gen3 x4 (Up to 3.94 GB/s) | 8x higher host transfer bandwidth prevents frame stalling. |
| YOLOv8s Inference Latency | Unsupported (Requires hybrid CPU fallback) | 4.2 ms (Over 230 FPS Continuous) | Full native end-to-end execution without CPU handoffs. |
| Model Compiler Chain | edgetpu_compiler (TF Lite INT8 only) | Hailo Dataflow Compiler (ONNX, PyTorch) | Hailo allows exporting directly from PyTorch with zero TF tooling. |
The Compiler Wall: edgetpu_compiler vs Hailo Dataflow Compiler
The true operational bottleneck of the Google Coral is not just its raw hardware TOPS; it is the Edge TPU Compiler toolchain. The Coral compiler has been virtually abandoned by Google. It requires input models to be quantized strictly in TensorFlow Lite using Post-Training Quantization (PTQ) or Quantization-Aware Training (QAT). If a single mathematical operator in your neural network (such as a SiLU activation, multi-head attention slice, or dynamic shape reshape) is unsupported, the compiler either aborts or splits the model: running 70% of the model on the TPU and falling back to the host CPU for the remaining 30%. This CPU-to-TPU context switching completely destroys throughput.
In contrast, the Hailo Dataflow Compiler (HDC) represents the gold standard in modern edge tooling. HDC ingests industry-standard ONNX models exported directly from PyTorch. It features an automated Model Optimization Engine that performs advanced INT8 quantization with equalized layer scaling, ensuring less than 1% accuracy degradation compared to FP32 models. The compiler maps the entire network onto the Hailo-8 core grid in a unified binary (a .hef file), guaranteeing 100% on-chip execution with zero host CPU fallback.
Host CPU Overhead & DMA Ring Buffers: Eliminating PCIe Polling
A critical architectural difference often obscured by peak TOPS benchmarks is host CPU utilization. When running high-throughput object detection on the Google Coral Edge TPU, the host CPU must manage continuous buffer allocations, convert image formats (RGB to BGR), and service frequent device interrupts over PCIe Gen2. Under a 30 FPS 4K stream, an Intel Core i5 or AMD Ryzen host processor can spend 15% to 25% of its total cycles simply servicing Coral interrupt routines and copying frames across user-space memory buffers.
The Hailo-8 eliminates this host tax through zero-copy Direct Memory Access (DMA) ring buffers. Using HailoRT’s asynchronous streaming API, incoming video frames decoded by the host GPU (via QuickSync or NVDEC) are mapped directly into physical DMA memory. The Hailo-8 fetches the image data directly over PCIe Gen3 x4 without intermediate host CPU context switching. Host CPU utilization remains under 2% to 4% even when processing 16 simultaneous camera feeds, leaving host processor cores completely free for database indexing, business logic, and web client streaming.
Hailo-8 Multi-Model Pipelines: Concurrent Vision Networks on One Chip
In production surveillance and robotics installations, a single object detector is rarely sufficient. A robust system requires cascading inference: first detecting vehicles with YOLOv8, then cropping bounding boxes and feeding them into a secondary network for license plate recognition (LPR), while simultaneously running a pose-estimation model on human pedestrians.
Attempting this on a Google Coral is disastrous: because the Coral can hold only one neural model in its limited internal SRAM at a time, switching models requires evicting the current model and loading a new binary over PCIe. This model-swapping latency takes 35 to 85 milliseconds per frame, causing massive frame dropouts. The Hailo-8 features a generous multi-network scheduler and segmented SRAM partitioning. You can compile multiple independent networks into a unified multi-context application, allowing the silicon to execute YOLOv8 detection, license plate OCR, and pose estimation sequentially within the exact same 10-millisecond frame window with zero reload latency.
PCIe Slot Geometry & Thermal Throttling Traps in Mini PCs
When retrofitting edge accelerators into compact x86 mini PCs (such as Lenovo Tiny, HP EliteDesk, or Intel NUCs), physical slot geometry presents serious pitfalls:
- M.2 Key Pinout Mismatches: The Google Coral is widely available in M.2 Key A+E (typically used for Wi-Fi slots) and Key B+M. The Hailo-8 is primarily manufactured in M.2 Key M 2280 or 2242 form factors designed for NVMe storage slots. Attempting to install a Key M Hailo-8 into an E-key Wi-Fi slot requires a passive riser adapter that often violates mini PC chassis clearances.
- Thermal Dissipation Realities: While the Hailo-8 consumes an average of 2.5W during continuous YOLOv8 inference, peak bursts can reach 5.0W. In an enclosed mini PC chassis without direct airflow, the uncooled silicon will reach its thermal junction ceiling (85°C) within 20 minutes, triggering aggressive clock throttling. Always install a finned aluminum thermal pad heatsink on the Hailo-8 module to maintain continuous maximum TOPS throughput.
Systems Checklist: Integrating Hailo-8 into Local Docker & Linux Stacks
- Kernel Driver Verification: Install the official Hailo PCIe driver (
hailo-pci) and firmware packages from the Hailo repository. Verify card detection usinghailortcli scan, confirming PCIe Gen3 x4 link negotiation. - Deploy HailoRT Microservices: Utilize HailoRT (Hailo Runtime) to manage multi-process inference. Configure shared PCIe access so that multiple Docker containers (e.g., Frigate NVR and a custom OpenCV microservice) can query the accelerator concurrently without device locks.
- Model Selection for Video: Deploy
yolov8s_h8.heffor standard object tracking oryolov8m_h8.heffor challenging long-range perimeter surveillance. The Hailo-8 easily sustains 30 FPS across 16 camera sub-streams simultaneously.
Frequently Asked Questions About Edge Vision Accelerators
Can I use a Hailo-8 in Home Assistant and Frigate NVR?
Yes. Frigate NVR 0.14+ includes native support for Hailo-8 and Hailo-8L accelerators via the official HailoRT integration, providing a seamless drop-in replacement for Google Coral TPUs.
What is the difference between Hailo-8 and Hailo-8L?
The Hailo-8L is a cost-reduced variant delivering 13 TOPS (featured on the Raspberry Pi AI Kit), while the full Hailo-8 delivers 26 TOPS with four times the internal SRAM capacity for complex models.
Does the Google Coral support Large Language Models (LLMs)?
No. The Google Coral Edge TPU lacks the memory architecture and operator support required to run autoregressive Large Language Models. Hailo-8 is likewise optimized for CNNs and vision transformers, not generative LLMs.
High-Throughput PCIe Accelerators & Carrier Cards
Accelerators require dedicated PCIe slot bifurcation and high-bandwidth carrier adapters. Explore multi-TPU carrier integration in our hardware guide on Coral Dual Edge TPU: PCIe Bifurcation & Frigate Guide.
Dual-core TPU hardware setup pairs directly with selecting the right edge AI accelerator. Review real-world TOPS benchmarks in our analysis on Google Coral Dual TPU: PCIe Bifurcation & Driver Guide.